FaunaDesk is live in veterinary practice. Dental and hospital editions are in development — see FaunaDesk

Straight from the engineers who shipped it.

Five long reads on AI calling agents, multi-tenant SaaS, ERP migrations, dashboards and custom software. No fluff. What worked, and what broke.

Five long reads on the work we actually do — AI tele-calling agents that complete tasks rather than take messages, multi-tenant SaaS that survives its first hundred customers, ERP migrations that do not stall in month four, dashboards people open at eight in the morning, and custom software for the process nobody sells a product for. Written by the engineers who shipped them.

Glowing cyan to violet audio waveform on a black starfield, representing an AI tele-calling agent processing a live phone call
Latency is the whole product: an AI voice agent lives or dies inside 900 milliseconds.
9 min readGatridge Engineering

Building an AI tele-calling agent that completes the task

Every business we work with has the same silent leak. Somebody calls the veterinary clinic at 7:40pm to move an appointment, hears six rings and a voicemail greeting, hangs up, and books with whoever answers next. Nobody logs it. It never shows on a report. At the end of the quarter the owner sees revenue slightly below target and blames the market.

An AI tele-calling agent is the cheapest fix for that leak, and also the easiest thing in modern software to build badly. Demos are trivial: wire speech recognition to a language model, pipe the reply through a text-to-speech engine, and you have something that talks. Putting that on a real phone line, in a room with a dishwasher running, in front of a caller with an accent and a toddler, is a different discipline entirely.

This is how we build them, what breaks, and the numbers we hold ourselves to.

The latency budget is the architecture

Humans tolerate about 800 milliseconds of silence in conversation before they assume something is wrong. They start repeating themselves, they say "hello?", they hang up. Every architectural decision in a voice agent falls out of that single number, so we write the budget down before we write any code.
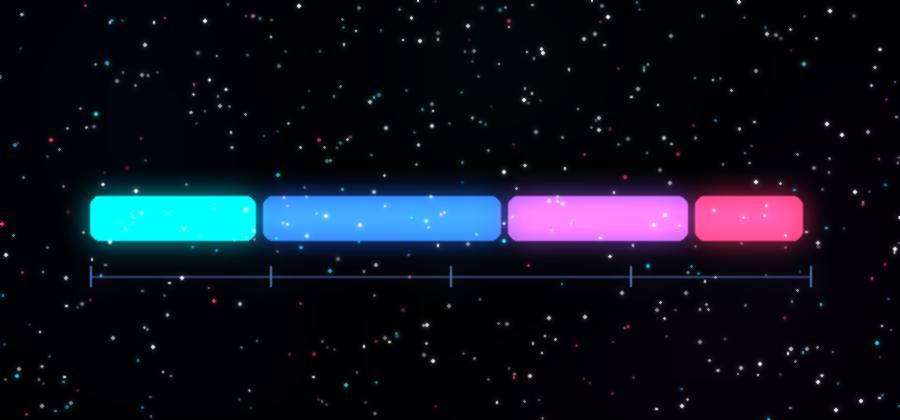
Coloured timeline segments showing the latency budget of an AI voice agent split across speech recognition, language model, text to speech and network transport
StageBudgetWhat blows it
Endpointing120 msWaiting for silence instead of predicting turn-end
Speech to text200 msBatch transcription rather than streaming partials
Reasoning300 msOversized prompts, sequential tool calls, no streaming
Text to speech180 msGenerating the whole sentence before playback starts
Transport100 msRegion hops between telephony and inference

The trick that buys most of the headroom is refusing to work in sequence. Transcription streams partial words while the caller is still speaking. The model starts drafting on those partials. Speech synthesis begins on the first clause while the rest is still being generated. By the time the caller stops talking, the first syllable of the answer is already on the wire.

Barge-in, or how to sound human

The single feature that separates a convincing agent from an obvious robot is barge-in: the caller interrupts, and the agent stops mid-word and listens. It sounds small. It requires full duplex audio, echo cancellation so the agent does not transcribe its own voice, and the discipline to discard the half-spoken response and re-plan from what the caller actually said.

Get it wrong and you produce the worst experience in the category — a system that talks over a frustrated human. We treat interrupt latency as a hard requirement and measure it in every release.

Answering is not the job. Completing is.

A voice agent that takes a message has moved work, not removed it. Somebody still opens the inbox at nine the next morning and calls back. Our threshold for shipping is that the agent finishes the task inside the call and writes it back to the system of record before the line drops.

  • Booking: reads live availability, holds the slot during the conversation, confirms it, releases the hold if the caller changes their mind.
  • Rescheduling and cancellation: identifies the caller, applies your notice policy, frees the slot for the waiting list automatically.
  • Outbound reminders and recalls: vaccination due, six-month dental check, table confirmation the afternoon before, invoice past thirty days.
  • Qualification: captures what the enquiry is about and routes it to the right person with a summary already attached.
  • Escalation: hands to a human on request, on repeated confusion, or on any word that suggests an emergency.
The metric that matters is not calls answered. It is tasks closed without a human touching them — and we report it per intent, because an agent can be excellent at bookings and useless at billing questions.

Escalation is a safety feature

In healthcare-adjacent settings this is not optional. A veterinary line gets calls about a dog that has eaten chocolate. A dental line gets facial swelling. The agent needs a hard-coded triage layer that recognises urgency vocabulary and transfers immediately, before any model reasoning happens. We build that as a deterministic rule set, not as a prompt instruction, because prompts drift and rules do not.

What it costs to run, honestly

Per-minute cost is dominated by inference, not telephony. Self-hosting the speech and language stack lowers marginal cost significantly at volume and raises operational burden — you now own GPU capacity planning and model updates. Managed APIs invert that trade. For most clients under roughly two hundred calls a day, managed wins; above it, a hybrid does. We model both before recommending either, and we show the working.

How we roll it out

Never as a big-bang replacement of a phone line. Week one, the agent takes overflow only — calls that would have hit voicemail anyway, where the alternative is nothing. Week three, it takes after-hours in full. Week six, it fronts the line during business hours with instant transfer available. Every stage is measured against the previous one, and the rollback is a single configuration change.

The result our clients notice first is not the technology. It is that the front desk stops flinching when the phone rings during a consultation.

Accents, noise and names nobody spells the same way

Generic speech recognition is excellent at generic English and mediocre at the words your business actually uses. A veterinary line needs to hear "Frontline", "Bravecto" and a spaniel called Nyx. A dental line needs "periodontitis" and a surname the caller has been spelling out for people their entire life. A restaurant needs the name of a dish that exists in no dictionary.

We handle this with vocabulary biasing rather than hope: your service list, staff names, product catalogue and top two thousand customer surnames are loaded as recognition hints, and confidence thresholds are set per field. Where confidence drops below the threshold on something expensive to get wrong — a date, a phone number, a dosage — the agent confirms explicitly instead of guessing. Digits are grouped the way humans say them. Spellings are read back in the phonetic alphabet when the caller is clearly spelling.

Background noise is the other half of the problem. Kitchens, waiting rooms and car speakerphones are not test conditions, they are the normal case, so we evaluate against recordings from the client's own line rather than clean studio samples. A model that scores well on clean audio and badly at 40 decibels of ambient clatter is a model that fails on a Friday evening.

What we report every week after go-live

An agent that nobody measures drifts quietly. These are the six numbers we put in front of clients, and the thresholds at which we act on them.

  • Containment rate: the share of calls resolved without a human. Useful, but meaningless alone — an agent can contain a call by frustrating someone into hanging up.
  • Task completion by intent: booked, rescheduled, cancelled, answered, qualified. Reported separately, because averages hide the intent that is broken.
  • Transfer rate and reason: requested, repeated confusion, out of scope, urgency detected. Rising confusion transfers means the model needs work; rising out-of-scope means the scope was drawn too tightly.
  • Recognition accuracy on your vocabulary: not the vendor's published benchmark. Yours, on your terms, sampled weekly.
  • Time to first word: the latency the caller actually experiences, at the ninety-fifth percentile, not the average.
  • Abandonment inside the first ten seconds: the clearest signal that people do not want to talk to it.

Recording, consent and what happens to the audio

Voice systems collect some of the most sensitive data a business holds. In healthcare-adjacent settings, a call recording can contain clinical detail; in any setting it contains names, numbers and payment discussion. Consent announcements need to match the jurisdiction, and "this call may be recorded" is not a substitute for a lawful basis.

We default to a conservative posture: audio retained only as long as the client's policy requires, transcripts redacted for card numbers and identifiers before they reach any log, storage in the client's region, and a documented deletion path that someone can actually execute when a caller asks. If a client wants a shorter retention window than we propose, we shorten it. Nobody has ever regretted holding less voice data.

What an AI tele-calling agent should not do

It should not diagnose. It should not negotiate a bill. It should not attempt to retain an angry customer. It should not pretend to be human when asked directly — we answer that question honestly every time, and in three years of deployments that honesty has never once cost a booking.

Drawing those lines narrowly at the start is what makes the rest of the system trustworthy. An agent that does five things reliably is worth more than one that attempts thirty and surprises you on a Sunday.

Frequently asked

How long does it take to deploy an AI tele-calling agent?
Four to six weeks for a single-site deployment covering bookings, rescheduling and enquiries, including integration with your calendar or practice management system. Multi-site or complex telephony estates take longer, usually eight to ten weeks.

Will it work with our existing phone number and system?
Yes. The agent sits in front of your existing number through your telephony provider, so the number your customers know does not change. Transfers hand back into your normal extensions.

What happens if the agent cannot handle a call?
It transfers to a human with a summary of the conversation already attached, so nobody has to ask the caller to start again. Escalation triggers include explicit requests, repeated confusion, and any urgency vocabulary we define with you upfront.

Which businesses get the most from it?
Anyone losing calls outside business hours or during busy periods — veterinary and dental clinics, hospitals, restaurant groups and travel agencies see the fastest payback, because a missed call there is a directly measurable lost booking.
Network of glowing cyan and violet nodes connected by faint lines on a dark starfield, representing multi-tenant SaaS architecture
Every node is a tenant. The lines between them are the decisions you cannot undo cheaply.
8 min readGatridge Engineering

Multi-tenant SaaS: the decisions you cannot reverse later

Most SaaS products are not killed by competitors. They are killed by an architectural choice made in the second week, by one developer, in a hurry, that becomes unremovable by customer forty. We have been called in to unpick enough of them to know which choices those are.

SaaS development is mostly ordinary engineering. What makes it distinct is that you are running one codebase against many customers' data simultaneously, and the cost of a mistake is not one angry user but a breach notification to all of them.

Choose your isolation model in week one

There are three viable patterns and one that seems clever and is not.

  • Shared schema with a tenant column. Cheapest to run, fastest to build, and the default we recommend for most products. The entire safety of the system rests on that column never being forgotten.
  • Schema per tenant. Cleaner separation, easy per-customer export, painful once migrations must run across nine hundred schemas.
  • Database per tenant. Correct answer for enterprise and regulated buyers who require it contractually. Expensive to operate below that threshold.
  • Ad hoc filtering in application code. Not a pattern. This is the one that leaks.
Diagram of connected nodes showing tenant isolation boundaries in a multi-tenant SaaS platform

Whichever you choose, enforce it at the lowest possible layer. Row-level security in the database beats a middleware check, which beats a convention in a code review. The rule we apply: if a junior developer can leak another tenant's data by forgetting a where-clause, the architecture is wrong, not the developer.

Assume every query will eventually be written by someone who has not read the onboarding document. Design so that the careless version is still safe.

Billing is a product surface, not a plugin

Teams bolt billing on at the end and spend the next year paying for it. Trials, proration, plan changes mid-cycle, usage overages, annual contracts with monthly invoicing, tax by jurisdiction, dunning when a card fails — each of these touches your data model, not just your payment provider. Metering in particular must be designed with the feature it meters, or you will be reconstructing usage from logs to answer a billing dispute.

Onboarding decides retention before the product does

The gap between signup and first genuine use is where most churn is decided. We build toward a specific, measurable moment — the first import completed, the first dashboard shared, the first call handled — and instrument everything before it. If a customer has not reached that moment in seven days, someone should know without being told.

Observability you can bill against

Per-tenant metrics are not a nice-to-have. When a customer says "it was slow yesterday", you need to answer with their latency, on their tenant, at that hour — not a global average that hides them. The same instrumentation later tells you which customers cost you money to serve, which is the difference between growing and growing broke.

The unglamorous list

  • Backups you have actually restored from, in a rehearsal, with a stopwatch running.
  • A tenant export that produces a usable file — because the buyer's procurement team will ask, and because it is the right thing to offer.
  • Feature flags per tenant, so a bad release affects one customer rather than all of them.
  • An audit log written at the same time as the change, not reconstructed from it.
  • A staging environment with realistic data volumes; a hundred rows hides every problem worth finding.

None of that appears on a landing page. All of it appears in the enterprise security questionnaire that decides your largest deal.

Data model choices that outlive every rewrite

Frameworks get replaced. Front ends get rebuilt every four years. The data model persists, and a handful of early decisions in it will either quietly support the product for a decade or generate bugs forever.

  • Identifiers: opaque, non-sequential keys externally. Sequential integers leak volume to competitors and invite enumeration.
  • Money: stored as integer minor units with an explicit currency, never as a floating point number. This is not pedantry; it is the difference between a reconciled ledger and a rounding investigation.
  • Time: stored in UTC, displayed in the tenant's zone, with the zone recorded against the record itself. Multi-site clients will have sites in different zones sooner than you expect.
  • Deletion: soft by default with a real purge path behind it, because "delete my data" is a legal obligation and a hard delete cascading through a live system is a Friday nobody enjoys.
  • History: append-only audit written in the same transaction as the change. Reconstructing history later from application logs is a project in itself.

The noisy neighbour problem

In a shared platform, one customer's bad afternoon becomes everyone's. A single tenant importing four hundred thousand rows, or running an unbounded report at nine on a Monday, will saturate a connection pool and degrade every other tenant on that instance. The first time this happens you will find out from a customer, not from a graph.

The defences are unglamorous and effective: per-tenant rate limits, query timeouts that fire before the pool exhausts, background work queued per tenant rather than globally, and heavy reporting served from a read replica or a pre-aggregated store. Combined with per-tenant metrics, this turns "the app is slow" into "tenant 412 is running an import, and here is the limit that stopped it spreading".

Entitlements deserve their own service

Plans, seats, feature flags, trial states and usage caps end up scattered across the codebase as conditionals if nobody owns them. Six months later, changing a price means editing eleven files and hoping. We build a single entitlements layer that every feature asks — can this tenant, on this plan, do this thing right now — so pricing and packaging become configuration rather than a release.

The commercial benefit shows up the first time a salesperson wants to offer a customised package to close an enterprise deal, and engineering can say yes the same afternoon.

The security questionnaire is a roadmap

Every serious buyer sends one, and the items that appear on all of them tell you what to build before you need it: single sign-on through SAML or OIDC, role-based access with a real permission model, an exportable audit trail, encryption at rest and in transit, documented backup and restore, a data processing agreement, breach notification commitments, and increasingly a recent penetration test.

Treat the enterprise questionnaire as a product backlog rather than a compliance chore. Every item on it is something your smaller customers benefit from too, and it is far cheaper to build early than to retrofit against a deadline with a signed contract waiting.

Knowing what a customer costs you

Usage-based infrastructure and flat-rate pricing are a dangerous combination if nobody is watching. We instrument compute, storage and third-party spend per tenant from launch, so gross margin is visible per customer rather than as one number at the end of the quarter. It is common to find that the largest account by revenue is not the largest by profit, and occasionally that a small number of customers consume a majority of the platform.

That knowledge changes pricing conversations from guesswork into arithmetic, and it arrives far too late if you start measuring after the first difficult board meeting.

Frequently asked

How long does it take to build a SaaS product?
A focused first release with authentication, the core workflow, billing and onboarding typically takes twelve to sixteen weeks. We aim for a usable internal build in the first fortnight so decisions are made against working software.

Should we start multi-tenant or add it later?
Start multi-tenant. Retrofitting tenancy into a single-tenant codebase touches every query, every background job and every migration, and it is one of the most expensive changes we are asked to make.

Can you take over an existing SaaS product?
Yes. We start with a two-week audit covering architecture, tenancy, security posture and deployment, then produce a prioritised plan with a cost against each item before touching the code.

Do you build the billing integration too?
Yes — subscriptions, trials, proration, usage metering, dunning and invoicing, integrated with your payment provider and reconciled against your accounting system.

Concentric coloured orbits with module markers circling a bright white core, representing ERP modules orbiting a single system of record
Finance, inventory, procurement and people on concentric orbits around one record.
8 min readGatridge Engineering

Why ERP implementations fail in month four, not month one

ERP projects rarely collapse at go-live. They collapse about four months in, when the excitement has worn off, the configuration decisions nobody wanted to make are still open, and the finance team has quietly gone back to the spreadsheet because the new system cannot yet produce a number they trust.

The failure is almost never technical. ERP implementation is a data and decision problem wearing a software costume.

Your data is worse than you think

Every organisation believes its master data is broadly fine. It never is. A typical first extract turns up the same supplier under four spellings, products with units of measure that changed meaning in 2019, customers who left in 2021 still marked active, and opening balances that reconcile only because someone posts an adjustment each month that nobody can explain.

We now run data profiling in week one, before configuration, because the findings change the plan. Cleansing is not preparation for the project. It is the project, for the first six weeks.

Concentric orbit diagram illustrating phased ERP rollout across finance, inventory, procurement and manufacturing modules

Configure to the process you have, then improve it

Two failure modes sit either side of this. Configure exactly to current process and you have paid to digitise thirty years of workarounds. Insist on best practice and you get a system nobody uses because it does not match how the warehouse actually receives goods on a Friday afternoon.

Our rule: match the current process for anything that touches money or compliance, and challenge everything else with evidence. "Why do we do it this way?" answered with "because Sandra set it up like that" is an invitation to change it.

The three questions that decide the project: who owns the item master, when does revenue get recognised, and what happens at the physical moment a good is received. Everything else is configuration.

Run parallel until it is boring

Big-bang cutovers survive in slide decks and rarely in warehouses. We run the legacy system alongside the new one for at least one full period, reconciling daily. The difference between the two is the defect list, and it must reach zero before cutover — not "close enough with a known variance", which is how a five-figure discrepancy becomes a year-end problem.

Phase by module, not by department

  • Phase one — finance core: chart of accounts, ledgers, AP and AR. Nothing else works until the ledger is trusted.
  • Phase two — inventory and procurement: item master, locations, purchase orders, goods receipt.
  • Phase three — operations: manufacturing, work orders, service jobs, whatever your actual business does.
  • Phase four — people and analytics: payroll integration, HR records, the reporting layer everyone assumed came first.

Each phase is live and useful on its own. If budget disappears after phase two — and sometimes it does — the client still has something that works rather than a half-built system and an invoice.

Where it lives

Cloud, private cloud or on-premise is usually settled by compliance rather than preference. What matters more is that the answer is chosen deliberately and that the deployment is reproducible. We have inherited too many ERP servers that exist as a single machine under a desk, configured by hand, by someone who left in 2018.

The month-four checklist

If four months in you cannot produce a trial balance from the new system without manual adjustment, if two people disagree about who owns the item master, or if anyone is still maintaining a parallel spreadsheet "just in case" — stop adding scope and fix those three things. Projects that address them recover. Projects that push forward do not.

Configuration or customisation: the upgrade path decides

Every ERP conversation eventually reaches a requirement the standard system does not cover. There are two ways to answer it, and the difference between them is felt three years later rather than three weeks later.

Configuration stays inside the vendor's supported envelope and survives upgrades. Customisation — modifying core objects, patching standard logic — solves today's problem and taxes every future release. Our rule is that customisation must clear a high bar: it is only justified when the process it supports is genuinely a competitive advantage, and even then it belongs in an extension layer with its own tests rather than in the core.

The organisations we meet that are stranded on an ERP version from 2016 are almost never there because of cost. They are there because eleven customisations make the upgrade a rewrite.

Integrations are where the estimate goes wrong

The ERP is never alone. It has to exchange data with the point of sale, the e-commerce store, the bank, the tax portal, the payroll provider, the freight partners and, in most cases, at least one system whose vendor no longer answers the phone. Each connection carries its own authentication, its own failure modes and its own idea of what a customer record is.

  • Establish the master: for every shared entity, exactly one system is authoritative. Two-way sync without a master is how duplicate suppliers are born.
  • Design for replay: integrations fail. Messages must be retryable without double-posting an invoice.
  • Monitor the quiet ones: the integration that stops silently is more damaging than the one that errors loudly. Alert on absence, not just on failure.
  • Version the contract: the partner will change their API without telling you. A versioned interface turns that into a scheduled task rather than an outage.

Change management is not a soft skill

The most technically sound implementation still fails if the warehouse team decides it is easier to keep the old clipboard. We budget for this explicitly: super users identified per department in week two, trained early and given real influence over configuration decisions; training delivered on the client's own data rather than a demo dataset; and floor-walking support in the first two weeks after each phase, physically standing where the work happens.

The signal that this is working is small and specific: people start asking for improvements to the new system instead of asking when the old one is coming back.

What it really costs over three years

Sticker price is licences. Real cost is licences plus implementation plus integration plus your own team's time plus the productivity dip in the first two months plus ongoing support and the annual upgrade. Internal time is the line most often left out of the business case, and it is frequently the largest single item — the finance lead who spends a day a week on this project for six months is a real cost even though no invoice records it.

We build the three-year model with clients before contracts are signed, including the uncomfortable numbers, because a project justified on an incomplete case is a project that loses support the moment it becomes difficult.

Frequently asked

How long does an ERP implementation take?
For a mid-sized business, four to nine months across phases, with the finance core live in roughly twelve weeks. Anyone promising a full multi-module ERP in six weeks is describing a demo, not a deployment.

Can you migrate us without stopping operations?
Yes. We run the legacy system in parallel with the new one and reconcile daily until the variance is zero, then cut over. Operations continue throughout, and the rollback path stays open until the first clean period close.

Do you implement an existing ERP product or build one?
Both, depending on the fit. Most businesses are better served by implementing and extending an established platform. We recommend a custom build only where the operating model genuinely has no market equivalent.

What happens to our old data?
It is profiled, cleansed, mapped and migrated with a documented audit trail, and the historical archive stays queryable. Nothing is discarded silently.

Abstract dashboard panel with gradient bar chart and white trend line on a dark starfield, representing operational dashboard development
A dashboard is not a report. It is the screen someone leaves open all day.
7 min readGatridge Engineering

Dashboard development for one site and for four hundred

Ask a practice owner what they need and they will say "a dashboard". Ask what they do every Monday morning and they will describe rebuilding the same spreadsheet from four exports. That spreadsheet is the specification. It is more honest than any requirements document, because somebody voluntarily does the work every week.

We start dashboard development by asking for that file rather than for a wish list.

Single site: the eight o'clock screen

For one clinic, one restaurant or one branch, the design constraint is brutal: whatever is on screen must be readable in the ten seconds before the first customer arrives. That usually means today's bookings against capacity, staff on shift versus planned, stock below reorder, revenue against target, and the follow-ups nobody has made yet.

Five things. Not forty. The fastest way to kill a dashboard is to make it comprehensive.

Layered chart panel illustrating role-based access control tiers across enterprise dashboard users

Enterprise: the same measure, everywhere

Multi-site changes the problem from presentation to definition. When four hundred locations report "utilisation", you will find at least six different formulas in the wild. Half your build is agreeing on one, and then making every site's raw data conform to it — including the two sites that will insist their version is correct.

  • Roll-up with drill-down: group number, region, site, individual record, in three clicks and never a dead end.
  • Comparison as a first-class view: ranked league tables, not a site selector that shows one at a time.
  • Role-based access: a branch manager sees their site; a regional sees their region; head office sees everything; nobody sees payroll who should not.
  • Definitions in the interface: hover any metric and read exactly how it is calculated and when it last refreshed.
If two people can look at the same number and disagree about what it counts, the dashboard has created an argument rather than settling one.

Live means live

A dashboard that refreshes overnight is a report with better styling. Where the source systems allow it we stream changes; where they do not, we are explicit about the lag and display it on screen. Silent staleness destroys trust faster than a missing feature — one decision made on yesterday's stock figure and nobody opens it again.

Build for the phone, seriously

Owners and regional managers do not check dashboards at a desk. They check them in a car park between sites. That is not a scaled-down version of the desktop layout; it is a different, smaller product with three numbers and one action. We design it first, then expand outward to the large screen.

What we hand over

The dashboard, the definitions, the pipeline that feeds it and the documentation for both. Clients own the source. We have replaced enough reporting layers that were hostages to their vendor to be firm about that one.

The pipeline nobody sees

A dashboard is the visible ten per cent. Underneath sits the part that determines whether it can be trusted: connectors to each source system, incremental synchronisation so you are not re-reading the entire history every fifteen minutes, a landing area holding raw data exactly as it arrived, and a modelling layer where business definitions live in one place.

That modelling layer matters more than any chart. When "revenue" is defined once, in code, with tests around it, every screen agrees. When it is defined in each chart separately, you have built a disagreement engine with excellent typography.

Alerts beat dashboards for anything urgent

Nobody watches a screen continuously. If something genuinely requires action within the hour — a site below half capacity at ten, stock hitting zero on a top seller, a payment run that failed — it should arrive as a notification, not wait to be discovered.

We pair every dashboard with a small set of thresholds and a daily digest. The digest is deliberately short: what changed, what needs a decision, what can wait. Teams that receive a three-line message each morning open the full dashboard more often, not less, because they trust it to tell them when it matters.

Adoption is a design problem

Dashboards die quietly. Six weeks after launch, usage halves; at three months only the person who commissioned it still opens it. The causes are consistent, and all of them are fixable at design time.

  • No owner per metric. If nobody is accountable for a number, nobody defends its accuracy, and one wrong figure discredits the whole screen.
  • Too many numbers. Forty tiles is an archive. Five is a tool.
  • No action attached. Every metric should imply a next step; if it does not, it belongs in a monthly report instead.
  • Unexplained staleness. Always show when the data last refreshed, even when the answer is embarrassing.
  • Desktop-only. The people who most need it are rarely at a desk.

What single-site and enterprise clients each ask for by month three

Single-site clients invariably ask for two things: a comparison against the same week last year, and a way to see which specific customers are behind a number. Enterprise clients ask for a different pair: an export that matches the board pack exactly, and permissions granular enough that a franchisee sees their own site and nothing else.

Knowing this in advance shapes the build. We now design the drill-through and the permission model in the first week rather than bolting them on in month four, because both are expensive to add late and trivial to include early.

Frequently asked

How long does dashboard development take?
A single-site operational dashboard is typically live in three to five weeks. Enterprise multi-site roll-ups take eight to twelve weeks, with most of that time spent agreeing metric definitions rather than building screens.

Can it read from the systems we already use?
Yes. We connect to practice management systems, point of sale, booking platforms, accounting packages and spreadsheets where an API does not exist. The dashboard reads from your sources; it does not require you to replace them.

How current is the data?
Live wherever the source system allows streaming or frequent polling. Where it does not, we state the lag on screen so nobody makes a decision on stale figures without knowing it.

Do we own the dashboard afterwards?
Yes — the dashboard, the pipeline that feeds it, the metric definitions and the documentation. You are free to maintain it in-house or with another partner at any point.

Blueprint grid with a glowing cyan path and violet waypoints, representing custom software development mapped to a business process
Custom software is worth it exactly where your process refuses to fit the grid.
7 min readGatridge Engineering

Custom software: when building beats buying

We turn down custom builds regularly. If a client's requirement is invoicing, or payroll, or a booking calendar with nothing unusual about it, a product already exists that is cheaper, better tested and available on Monday. Recommending a build there would be selling hours, not solving a problem.

Custom software development earns its cost in a narrower band than most agencies will admit — but inside that band, nothing else works.

Four conditions that justify building

  • The process is your advantage. If how you route jobs, price work or schedule capacity is why customers choose you, buying software forces you into your competitors' shape.
  • The integration is the product. Five systems that must agree in real time. No vendor optimises for your specific five.
  • The licence maths has inverted. Per-seat pricing across four hundred staff, most of whom use one screen, eventually exceeds the cost of owning it.
  • Nobody serves your vertical properly. Mobile veterinary practices, multi-branch travel operators, franchised kitchens — real businesses in markets too small for a major vendor to bother with.
Blueprint style diagram of a custom software stack path connecting existing systems through integration waypoints

Buy the boring parts

Custom does not mean writing everything. We buy authentication, payments, email delivery, document generation and error tracking in almost every project. Custom effort belongs on the twenty per cent that is genuinely yours; the rest is solved, cheap and someone else's maintenance burden.

The question is never "build or buy". It is which twenty per cent to build, and how little you can get away with owning.

Replace legacy in slices

A fifteen-year-old system usually cannot be replaced in one release, and the attempt is how two-year projects are born. We put a routing layer in front of the old system and move one capability at a time behind it. Users keep working throughout. Each slice is reversible. The old system shrinks until switching it off is uneventful rather than terrifying.

What you should own at the end

Source code, in your repository. Infrastructure defined as code, in your account. Documentation written for the developer who inherits it, not for the invoice. A deployment any competent engineer can run without calling us.

We would rather be retained because the work is good than because leaving is expensive. Every client we have kept for more than three years has been free to walk away at any point.

How to start without committing

Two weeks, fixed price, one outcome: a working prototype of the hardest screen with your real data in it, plus an honest estimate of the whole. If the estimate frightens you, you have spent two weeks finding that out instead of six months. If it does not, you already have the first piece built.

How we estimate, and why ranges beat single numbers

A single-figure estimate is a marketing device. Software estimates carry genuine uncertainty, and the honest way to express it is a range that narrows as the unknowns close. We break work into slices small enough to be delivered inside a fortnight, estimate each as a range, and attach the specific question that would tighten it.

The largest variances almost always sit in the same three places: integration with a system we cannot inspect until we have credentials, data migration from a source nobody has profiled, and approval processes that turn out to have exceptions nobody documented. We surface those three at the start and price the discovery separately, so the number you approve for the build is the number you pay.

The shape of the team matters more than the headcount

Adding people to a late project is famously ineffective, but the more common failure is a team assembled from whoever was free. Our pods are deliberately small: a lead engineer who stays for the whole engagement, two engineers, a designer for the first half, and quality assurance shared across projects.

The lead engineer is the important part. Continuity of the person who understands why a decision was made is worth more than an extra pair of hands, and it is the reason handover documents are a supplement in our projects rather than the only surviving knowledge.

Maintenance is a line item, not an afterthought

Custom software needs roughly fifteen to twenty per cent of its build cost each year to stay healthy: dependency updates, security patches, small changes as the business shifts, and the occasional integration that breaks because a partner changed their API on a Tuesday.

Clients who budget for that get a system that is still good in year five. Clients who do not get one that quietly ages until the word "legacy" appears in a meeting, and then pay for the replacement they were trying to avoid. We put the figure in the original proposal even though it makes the total look larger, because the alternative is a pleasant conversation now and an unpleasant one later.

Compliance is cheaper when it is designed in

Clinics, hospitals and anyone handling patient or payment data carry obligations that shape architecture: where data lives, who can reach it, how access is logged, how long records are retained, and what must happen when someone asks for their data to be removed.

Every one of those is straightforward to build in from the first week and expensive to retrofit under audit pressure. We treat data residency, encryption, role-based access, audit logging and a working deletion path as baseline requirements on every project, including the ones where the client has not asked for them yet.

A fortnight is enough to know

The most useful thing we do for a prospective client costs two weeks. We take the hardest screen in the proposed system — the one everybody is uncertain about — and build it properly with their real data, then estimate the remainder with that experience behind us.

Sometimes the outcome is that we recommend an off-the-shelf product and no further work. That has happened often enough that we consider it part of the service rather than a failure of one.

Frequently asked

How much does custom software development cost?
It depends on scope, but a focused first release delivering one complete workflow usually lands in the range a mid-sized business spends on a year of licences for the product it was trying to avoid. We give a range with the assumptions written down, not a single figure.

Do we own the source code?
Yes, entirely. Source in your repository, infrastructure defined as code in your account, and documentation written for whoever inherits it. There is no lock-in clause in our contracts.

Can you work alongside our in-house developers?
Yes. Many of our engagements are joint teams, with our engineers leading the first phase and handing progressively to the client's team as it grows.

What if we already started and it went wrong?
That is a large part of our work. We audit what exists, tell you honestly what is salvageable, and give you a cost to finish it and a cost to restart, so the decision is yours with real numbers behind it.

Bring us the project that stalled

Whether it is a phone line nobody answers after six, an ERP that never reached month five, or a dashboard your team rebuilds by hand every Monday — tell us what did not work. We will show you a working version inside a fortnight.